library(multinma)
options(mc.cores = parallel::detectCores())
#> For execution on a local, multicore CPU with excess RAM we recommend calling
#> options(mc.cores = parallel::detectCores())
#>
#> Attaching package: 'multinma'
#> The following objects are masked from 'package:stats':
#>
#> dgamma, pgamma, qgammaThis vignette describes the analysis of smoking cessation data (Hasselblad
1998), replicating the analysis in NICE Technical Support
Document 4 (Dias et al.
2011). The data are available in this package as
smoking:
head(smoking)
#>   studyn trtn                   trtc  r   n
#> 1      1    1        No intervention  9 140
#> 2      1    3 Individual counselling 23 140
#> 3      1    4      Group counselling 10 138
#> 4      2    2              Self-help 11  78
#> 5      2    3 Individual counselling 12  85
#> 6      2    4      Group counselling 29 170
Setting up the network
We begin by setting up the network. We have arm-level count data
giving the number quitting smoking (r) out of the total
(n) in each arm, so we use the function
set_agd_arm(). Treatment “No intervention” is set as the
network reference treatment.
smknet <- set_agd_arm(smoking,
                      study = studyn,
                      trt = trtc,
                      r = r,
                      n = n,
                      trt_ref = "No intervention")
smknet
#> A network with 24 AgD studies (arm-based).
#>
#> ------------------------------------------------------- AgD studies (arm-based) ----
#>  Study Treatment arms
#>  1     3: No intervention | Group counselling | Individual counselling
#>  2     3: Group counselling | Individual counselling | Self-help
#>  3     2: No intervention | Individual counselling
#>  4     2: No intervention | Individual counselling
#>  5     2: No intervention | Individual counselling
#>  6     2: No intervention | Individual counselling
#>  7     2: No intervention | Individual counselling
#>  8     2: No intervention | Individual counselling
#>  9     2: No intervention | Individual counselling
#>  10    2: No intervention | Self-help
#>  ... plus 14 more studies
#>
#>  Outcome type: count
#> ------------------------------------------------------------------------------------
#> Total number of treatments: 4
#> Total number of studies: 24
#> Reference treatment is: No intervention
#> Network is connected
Plot the network structure.
plot(smknet, weight_edges = TRUE, weight_nodes = TRUE)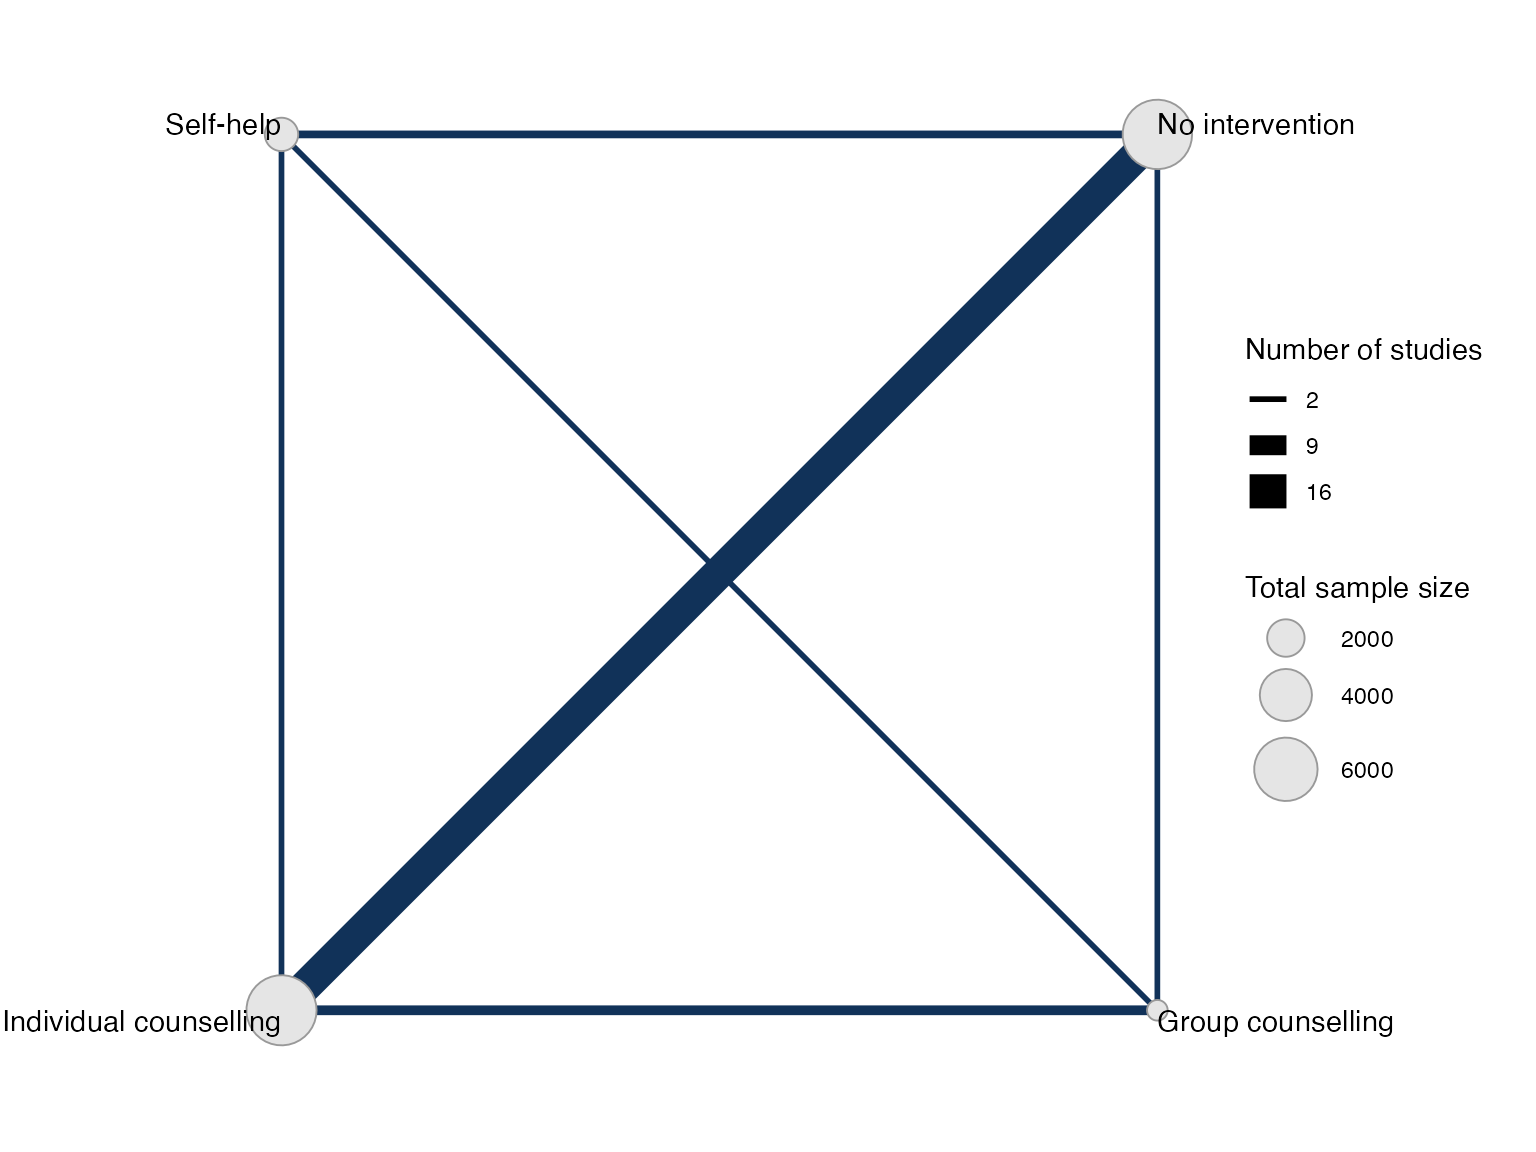
Random effects NMA
Following TSD 4, we fit a random effects NMA model, using the
nma() function with trt_effects = "random". We
use \mathrm{N}(0, 100^2) prior
distributions for the treatment effects d_k and study-specific intercepts \mu_j, and a \textrm{half-N}(5^2) prior distribution for
the between-study heterogeneity standard deviation \tau. We can examine the range of parameter
values implied by these prior distributions with the
summary() method:
summary(normal(scale = 100))
#> A Normal prior distribution: location = 0, scale = 100.
#> 50% of the prior density lies between -67.45 and 67.45.
#> 95% of the prior density lies between -196 and 196.
summary(half_normal(scale = 5))
#> A half-Normal prior distribution: scale = 5.
#> 50% of the prior density lies between 0 and 3.37.
#> 95% of the prior density lies between 0 and 9.8.
The model is fitted using the nma() function. By
default, this will use a Binomial likelihood and a logit link function,
auto-detected from the data.
smkfit <- nma(smknet,
              trt_effects = "random",
              prior_intercept = normal(scale = 100),
              prior_trt = normal(scale = 100),
              prior_het = normal(scale = 5))
Basic parameter summaries are given by the print()
method:
smkfit
#> A random effects NMA with a binomial likelihood (logit link).
#> Inference for Stan model: binomial_1par.
#> 4 chains, each with iter=2000; warmup=1000; thin=1;
#> post-warmup draws per chain=1000, total post-warmup draws=4000.
#>
#>                               mean se_mean   sd     2.5%      25%      50%      75%    97.5%
#> d[Group counselling]          1.11    0.01 0.44     0.28     0.81     1.10     1.39     2.02
#> d[Individual counselling]     0.85    0.01 0.24     0.39     0.69     0.83     0.99     1.35
#> d[Self-help]                  0.49    0.01 0.40    -0.30     0.23     0.48     0.73     1.30
#> lp__                      -5768.08    0.20 6.40 -5781.62 -5772.30 -5767.76 -5763.56 -5756.52
#> tau                           0.84    0.01 0.19     0.55     0.71     0.82     0.94     1.28
#>                           n_eff Rhat
#> d[Group counselling]       1710 1.00
#> d[Individual counselling]  1172 1.00
#> d[Self-help]               1730 1.00
#> lp__                        999 1.01
#> tau                        1174 1.00
#>
#> Samples were drawn using NUTS(diag_e) at Fri Oct  9 11:43:03 2026.
#> For each parameter, n_eff is a crude measure of effective sample size,
#> and Rhat is the potential scale reduction factor on split chains (at
#> convergence, Rhat=1).
By default, summaries of the study-specific intercepts \mu_j and study-specific relative effects
\delta_{jk} are hidden, but could be
examined by changing the pars argument:
The prior and posterior distributions can be compared visually using
the plot_prior_posterior() function:
plot_prior_posterior(smkfit)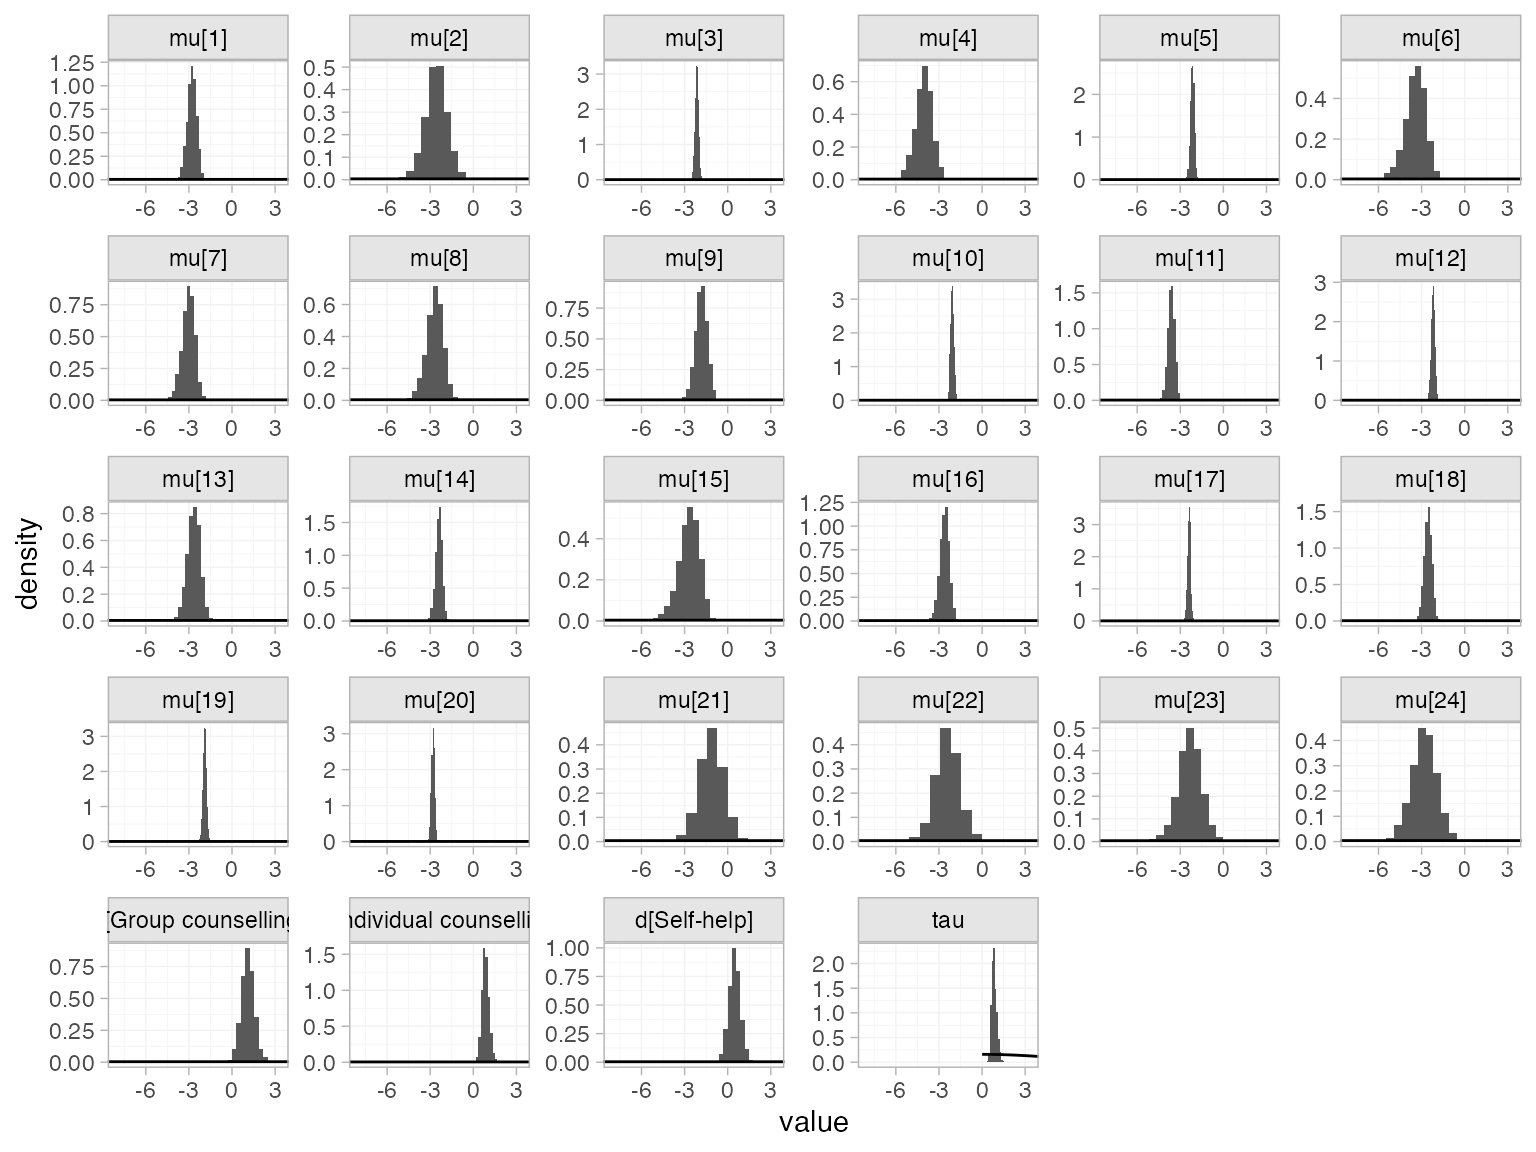
By default, this displays all model parameters given prior
distributions (in this case d_k, \mu_j, and \tau), but this may be changed using the
prior argument:
plot_prior_posterior(smkfit, prior = "het")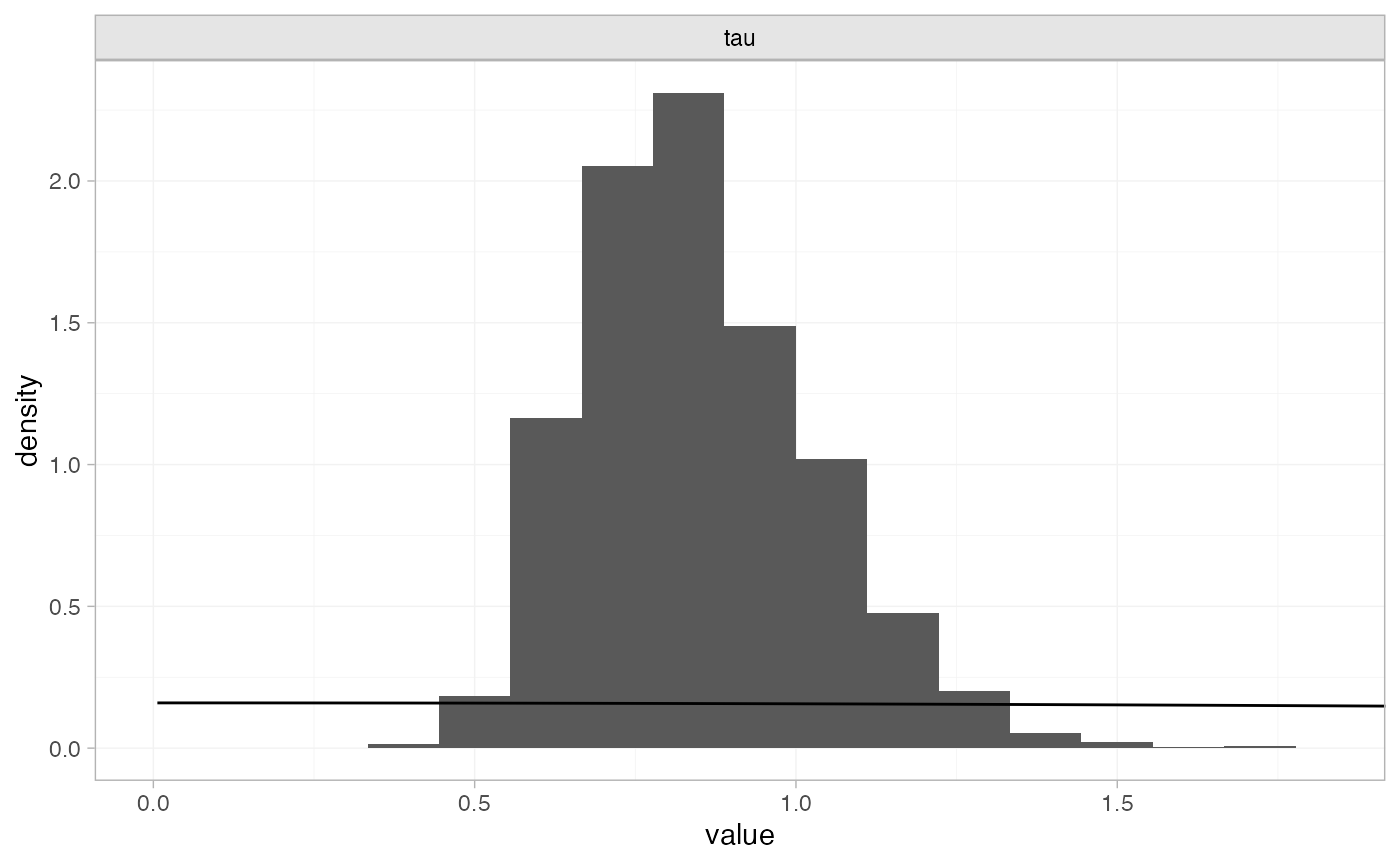
Model fit can be checked using the dic() function
(dic_consistency <- dic(smkfit))
#> Residual deviance: 54.4 (on 50 data points)
#>                pD: 44.1
#>               DIC: 98.4
and the residual deviance contributions examined with the
corresponding plot() method
plot(dic_consistency)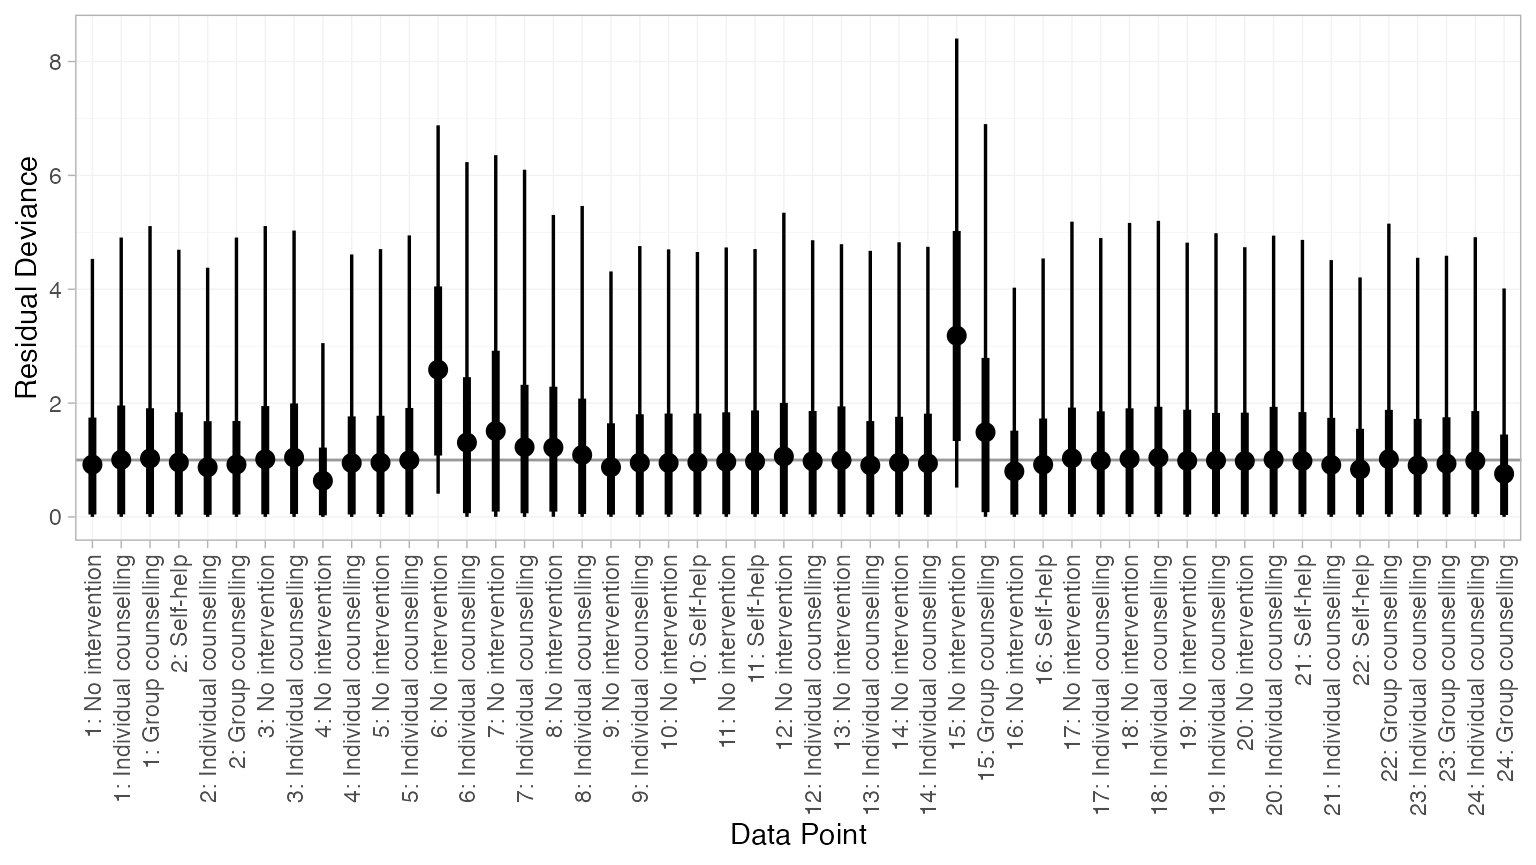
Overall model fit seems to be adequate, with almost all points showing good fit (mean residual deviance contribution of 1). The only two points with higher residual deviance (i.e. worse fit) correspond to the two zero counts in the data:
smoking[smoking$r == 0, ]
#>    studyn trtn            trtc r  n
#> 13      6    1 No intervention 0 33
#> 31     15    1 No intervention 0 20
Checking for inconsistency
Note: The results of the inconsistency models here are slightly different to those of Dias et al. (2010, 2011), although the overall conclusions are the same. This is due to the presence of multi-arm trials and a different ordering of treatments, meaning that inconsistency is parameterised differently within the multi-arm trials. The same results as Dias et al. are obtained if the network is instead set up with
trtnas the treatment variable.
Unrelated mean effects
We first fit an unrelated mean effects (UME) model (Dias et al. 2011) to
assess the consistency assumption. Again, we use the function
nma(), but now with the argument
consistency = "ume".
smkfit_ume <- nma(smknet,
                  consistency = "ume",
                  trt_effects = "random",
                  prior_intercept = normal(scale = 100),
                  prior_trt = normal(scale = 100),
                  prior_het = normal(scale = 5))
smkfit_ume
#> A random effects NMA with a binomial likelihood (logit link).
#> An inconsistency model ('ume') was fitted.
#> Inference for Stan model: binomial_1par.
#> 4 chains, each with iter=2000; warmup=1000; thin=1;
#> post-warmup draws per chain=1000, total post-warmup draws=4000.
#>
#>                                                     mean se_mean   sd     2.5%      25%
#> d[Group counselling vs. No intervention]            1.10    0.01 0.77    -0.33     0.61
#> d[Individual counselling vs. No intervention]       0.90    0.01 0.27     0.38     0.72
#> d[Self-help vs. No intervention]                    0.35    0.01 0.57    -0.79    -0.02
#> d[Individual counselling vs. Group counselling]    -0.29    0.01 0.61    -1.47    -0.69
#> d[Self-help vs. Group counselling]                 -0.61    0.01 0.72    -2.02    -1.07
#> d[Self-help vs. Individual counselling]             0.17    0.02 1.04    -1.88    -0.51
#> lp__                                            -5765.39    0.20 6.35 -5778.63 -5769.55
#> tau                                                 0.93    0.01 0.22     0.58     0.77
#>                                                      50%      75%    97.5% n_eff Rhat
#> d[Group counselling vs. No intervention]            1.07     1.58     2.71  2797    1
#> d[Individual counselling vs. No intervention]       0.89     1.07     1.48  1079    1
#> d[Self-help vs. No intervention]                    0.34     0.72     1.50  1839    1
#> d[Individual counselling vs. Group counselling]    -0.29     0.09     0.95  2430    1
#> d[Self-help vs. Group counselling]                 -0.61    -0.14     0.82  2306    1
#> d[Self-help vs. Individual counselling]             0.16     0.84     2.20  3597    1
#> lp__                                            -5764.98 -5760.81 -5754.28  1034    1
#> tau                                                 0.90     1.06     1.45  1300    1
#>
#> Samples were drawn using NUTS(diag_e) at Fri Oct  9 11:43:11 2026.
#> For each parameter, n_eff is a crude measure of effective sample size,
#> and Rhat is the potential scale reduction factor on split chains (at
#> convergence, Rhat=1).
Comparing the model fit statistics
dic_consistency
#> Residual deviance: 54.4 (on 50 data points)
#>                pD: 44.1
#>               DIC: 98.4
(dic_ume <- dic(smkfit_ume))
#> Residual deviance: 54 (on 50 data points)
#>                pD: 45.2
#>               DIC: 99.2
We see that there is little to choose between the two models.
However, it is also important to examine the individual contributions to
model fit of each data point under the two models (a so-called “dev-dev”
plot). Passing two nma_dic objects produced by the
dic() function to the plot() method produces
this dev-dev plot:
plot(dic_consistency, dic_ume, point_alpha = 0.5, interval_alpha = 0.2)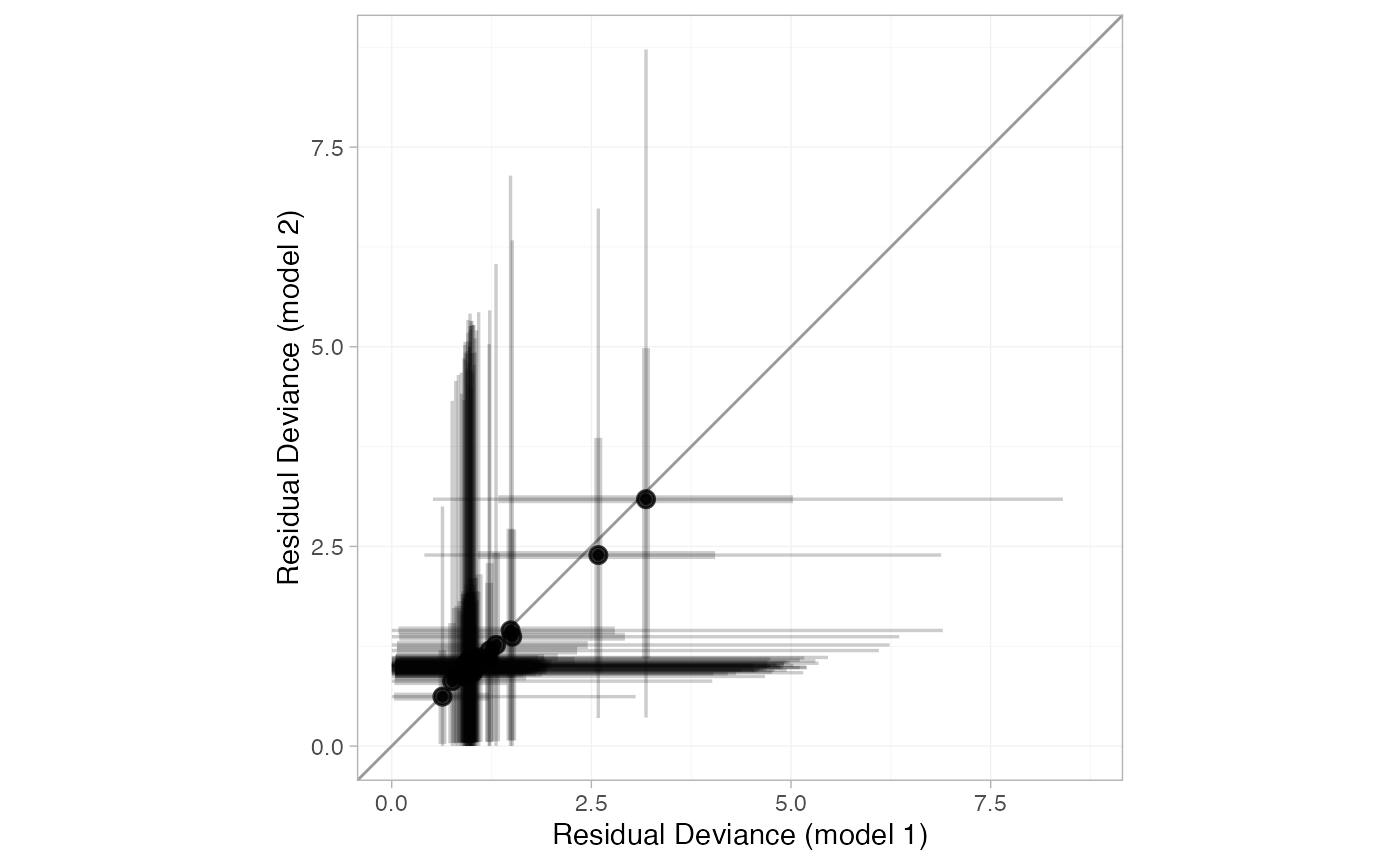
All points lie roughly on the line of equality, so there is no evidence for inconsistency here.
Node-splitting
Another method for assessing inconsistency is node-splitting (Dias et al. 2011, 2010). Whereas the UME model assesses inconsistency globally, node-splitting assesses inconsistency locally for each potentially inconsistent comparison (those with both direct and indirect evidence) in turn.
Node-splitting can be performed using the nma() function
with the argument consistency = "nodesplit". By default,
all possible comparisons will be split (as determined by the
get_nodesplits() function). Alternatively, a specific
comparison or comparisons to split can be provided to the
nodesplit argument.
smk_nodesplit <- nma(smknet,
                     consistency = "nodesplit",
                     trt_effects = "random",
                     prior_intercept = normal(scale = 100),
                     prior_trt = normal(scale = 100),
                     prior_het = normal(scale = 5))
#> Fitting model 1 of 7, node-split: Group counselling vs. No intervention
#> Fitting model 2 of 7, node-split: Individual counselling vs. No intervention
#> Fitting model 3 of 7, node-split: Self-help vs. No intervention
#> Fitting model 4 of 7, node-split: Individual counselling vs. Group counselling
#> Fitting model 5 of 7, node-split: Self-help vs. Group counselling
#> Fitting model 6 of 7, node-split: Self-help vs. Individual counselling
#> Fitting model 7 of 7, consistency model
The summary() method summarises the node-splitting
results, displaying the direct and indirect estimates d_\mathrm{dir} and d_\mathrm{ind} from each node-split model,
the network estimate d_\mathrm{net}
from the consistency model, the inconsistency factor \omega = d_\mathrm{dir} - d_\mathrm{ind}, and
a Bayesian p-value for inconsistency on
each comparison. Since random effects models are fitted, the
heterogeneity standard deviation \tau
under each node-split model and under the consistency model is also
displayed. The DIC model fit statistics are also provided.
summary(smk_nodesplit)
#> Node-splitting models fitted for 6 comparisons.
#>
#> ------------------------------ Node-split Group counselling vs. No intervention ----
#>
#>                  mean   sd  2.5%   25%   50%  75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net            1.10 0.43  0.28  0.81  1.09 1.39  1.94     1918     2630    1
#> d_dir            1.06 0.74 -0.35  0.56  1.03 1.52  2.58     3082     2935    1
#> d_ind            1.12 0.55  0.03  0.76  1.11 1.47  2.23     1666     2335    1
#> omega           -0.06 0.90 -1.76 -0.65 -0.09 0.50  1.81     2284     2426    1
#> tau              0.87 0.20  0.56  0.73  0.84 0.98  1.33     1265     1710    1
#> tau_consistency  0.84 0.18  0.53  0.71  0.82 0.94  1.25     1269     1900    1
#>
#> Residual deviance: 53.8 (on 50 data points)
#>                pD: 43.9
#>               DIC: 97.8
#>
#> Bayesian p-value: 0.92
#>
#> ------------------------- Node-split Individual counselling vs. No intervention ----
#>
#>                 mean   sd  2.5%   25%  50%  75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net           0.84 0.25  0.38  0.68 0.84 0.99  1.36     1231     1860    1
#> d_dir           0.88 0.26  0.39  0.71 0.87 1.05  1.42     1989     2247    1
#> d_ind           0.58 0.67 -0.71  0.14 0.56 1.01  1.92     1744     2309    1
#> omega           0.30 0.69 -1.08 -0.13 0.31 0.76  1.62     1728     2383    1
#> tau             0.86 0.19  0.56  0.73 0.84 0.97  1.31     1257     1957    1
#> tau_consistency 0.84 0.18  0.53  0.71 0.82 0.94  1.25     1269     1900    1
#>
#> Residual deviance: 54 (on 50 data points)
#>                pD: 44.1
#>               DIC: 98.1
#>
#> Bayesian p-value: 0.64
#>
#> -------------------------------------- Node-split Self-help vs. No intervention ----
#>
#>                  mean   sd  2.5%   25%   50%  75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net            0.48 0.41 -0.33  0.21  0.48 0.75  1.28     1749     1996    1
#> d_dir            0.33 0.56 -0.77 -0.01  0.33 0.68  1.42     3399     2506    1
#> d_ind            0.72 0.65 -0.52  0.31  0.71 1.10  2.06     1896     2171    1
#> omega           -0.38 0.85 -2.09 -0.92 -0.37 0.17  1.28     2144     2370    1
#> tau              0.87 0.21  0.56  0.73  0.84 0.99  1.33     1236     1692    1
#> tau_consistency  0.84 0.18  0.53  0.71  0.82 0.94  1.25     1269     1900    1
#>
#> Residual deviance: 53.6 (on 50 data points)
#>                pD: 44.1
#>               DIC: 97.7
#>
#> Bayesian p-value: 0.64
#>
#> ----------------------- Node-split Individual counselling vs. Group counselling ----
#>
#>                  mean   sd  2.5%   25%   50%   75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net           -0.26 0.41 -1.06 -0.52 -0.25  0.01  0.53     2663     2607    1
#> d_dir           -0.11 0.49 -1.10 -0.42 -0.11  0.22  0.84     3498     3043    1
#> d_ind           -0.53 0.61 -1.76 -0.93 -0.53 -0.13  0.66     1756     2203    1
#> omega            0.42 0.68 -0.90 -0.03  0.42  0.86  1.78     1842     2468    1
#> tau              0.86 0.19  0.56  0.72  0.83  0.96  1.30     1172     1691    1
#> tau_consistency  0.84 0.18  0.53  0.71  0.82  0.94  1.25     1269     1900    1
#>
#> Residual deviance: 54.1 (on 50 data points)
#>                pD: 44.2
#>               DIC: 98.3
#>
#> Bayesian p-value: 0.52
#>
#> ------------------------------------ Node-split Self-help vs. Group counselling ----
#>
#>                  mean   sd  2.5%   25%   50%   75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net           -0.62 0.48 -1.59 -0.93 -0.61 -0.30  0.31     2471     2648    1
#> d_dir           -0.63 0.66 -1.95 -1.04 -0.62 -0.21  0.65     4108     2762    1
#> d_ind           -0.61 0.69 -2.01 -1.05 -0.59 -0.16  0.69     2066     2513    1
#> omega           -0.02 0.88 -1.78 -0.59 -0.02  0.55  1.72     2295     2531    1
#> tau              0.88 0.20  0.56  0.73  0.85  0.98  1.34     1199     2031    1
#> tau_consistency  0.84 0.18  0.53  0.71  0.82  0.94  1.25     1269     1900    1
#>
#> Residual deviance: 53.8 (on 50 data points)
#>                pD: 44.1
#>               DIC: 97.9
#>
#> Bayesian p-value: 0.98
#>
#> ------------------------------- Node-split Self-help vs. Individual counselling ----
#>
#>                  mean   sd  2.5%   25%   50%   75% 97.5% Bulk_ESS Tail_ESS Rhat
#> d_net           -0.36 0.42 -1.21 -0.64 -0.36 -0.09  0.44     2087     2536 1.00
#> d_dir            0.07 0.66 -1.24 -0.33  0.06  0.49  1.36     2914     2774 1.00
#> d_ind           -0.62 0.53 -1.72 -0.96 -0.63 -0.27  0.43     1727     1920 1.00
#> omega            0.70 0.83 -0.93  0.17  0.70  1.22  2.36     1728     2332 1.00
#> tau              0.86 0.20  0.55  0.72  0.83  0.96  1.33     1037     1551 1.01
#> tau_consistency  0.84 0.18  0.53  0.71  0.82  0.94  1.25     1269     1900 1.00
#>
#> Residual deviance: 53.9 (on 50 data points)
#>                pD: 44.2
#>               DIC: 98.1
#>
#> Bayesian p-value: 0.38
The DIC of each inconsistency model is unchanged from the consistency model, no node-splits result in reduced heterogeneity standard deviation \tau compared to the consistency model, and the Bayesian p-values are all large. There is no evidence of inconsistency.
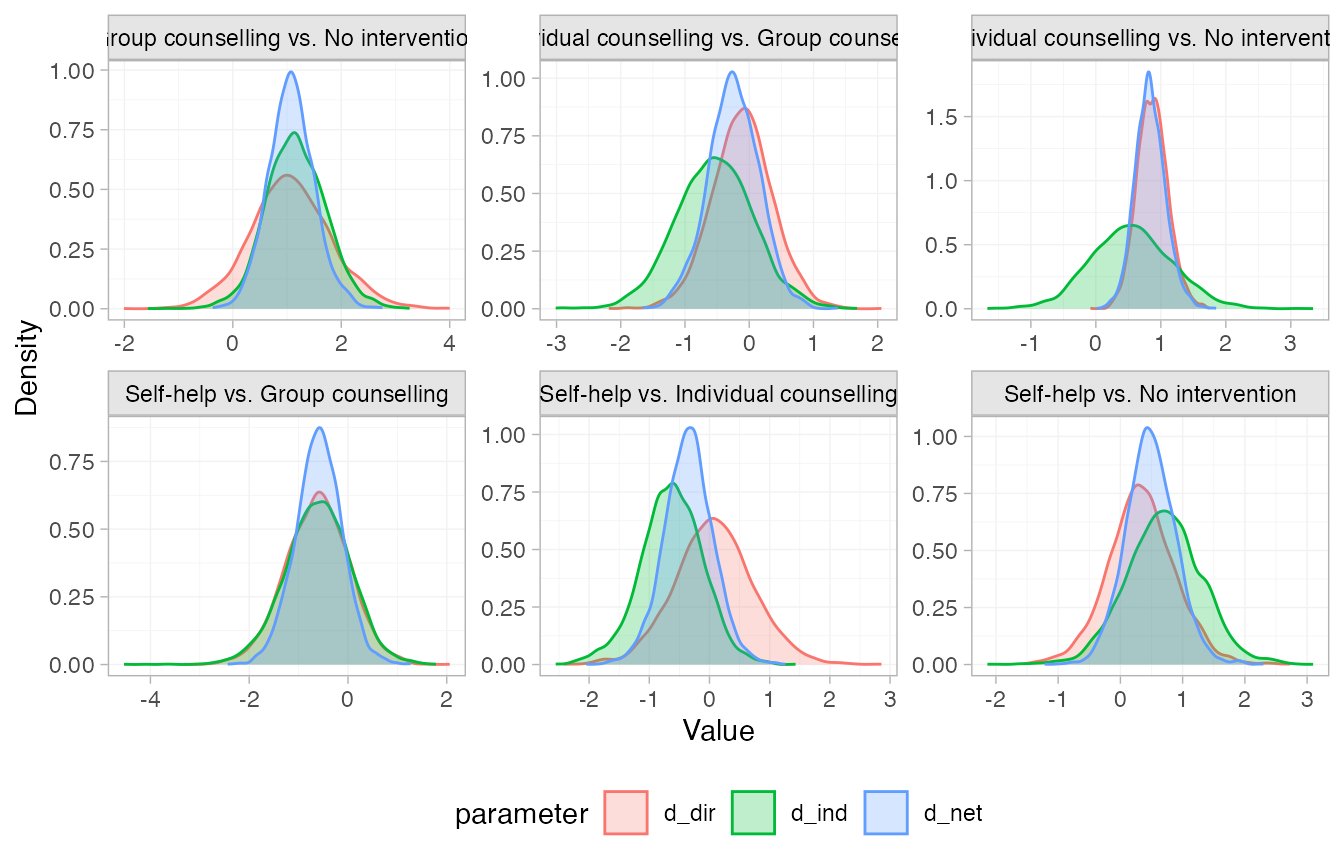
We can visually compare the posterior distributions of the direct,
indirect, and network estimates using the plot() method.
These are all in agreement; the posterior densities of the direct and
indirect estimates overlap. Notice that there is not much indirect
information for the Individual counselling vs. No intervention
comparison, so the network (consistency) estimate is very similar to the
direct estimate for this comparison.
Further results
Pairwise relative effects, for all pairwise contrasts with
all_contrasts = TRUE.
(smk_releff <- relative_effects(smkfit, all_contrasts = TRUE))
#>                                                  mean   sd  2.5%   25%   50%   75% 97.5%
#> d[Group counselling vs. No intervention]         1.11 0.44  0.28  0.81  1.10  1.39  2.02
#> d[Individual counselling vs. No intervention]    0.85 0.24  0.39  0.69  0.83  0.99  1.35
#> d[Self-help vs. No intervention]                 0.49 0.40 -0.30  0.23  0.48  0.73  1.30
#> d[Individual counselling vs. Group counselling] -0.26 0.43 -1.13 -0.54 -0.26  0.02  0.56
#> d[Self-help vs. Group counselling]              -0.62 0.48 -1.60 -0.93 -0.60 -0.29  0.28
#> d[Self-help vs. Individual counselling]         -0.36 0.41 -1.20 -0.62 -0.35 -0.10  0.44
#>                                                 Bulk_ESS Tail_ESS Rhat
#> d[Group counselling vs. No intervention]            1753     2034    1
#> d[Individual counselling vs. No intervention]       1207     1506    1
#> d[Self-help vs. No intervention]                    1751     2002    1
#> d[Individual counselling vs. Group counselling]     2515     2480    1
#> d[Self-help vs. Group counselling]                  2938     2707    1
#> d[Self-help vs. Individual counselling]             2218     2312    1
plot(smk_releff, ref_line = 0)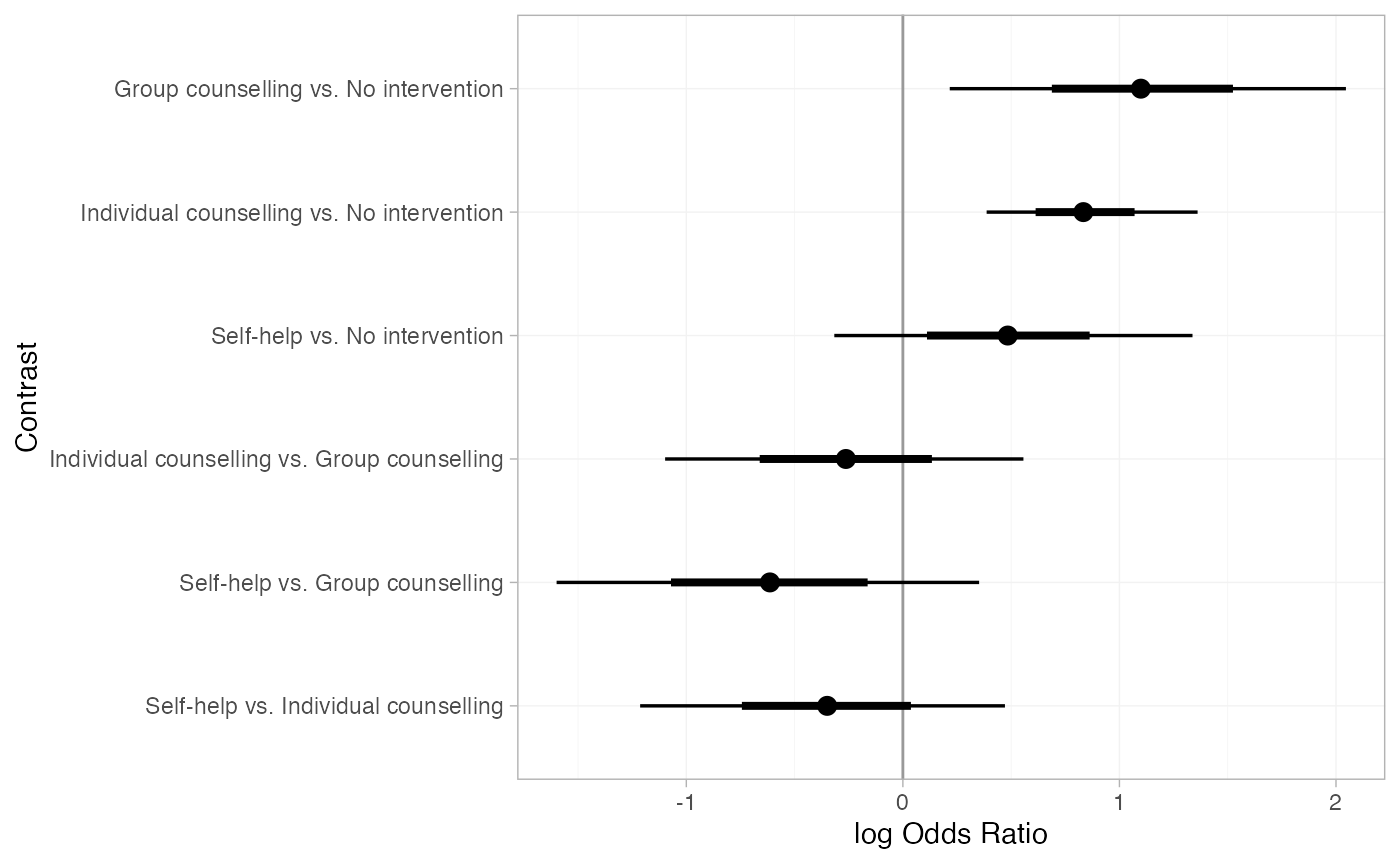
Treatment rankings, rank probabilities, and cumulative rank
probabilities. We set lower_better = FALSE since a higher
log odds of cessation is better (the outcome is positive).
(smk_ranks <- posterior_ranks(smkfit, lower_better = FALSE))
#>                              mean   sd 2.5% 25% 50% 75% 97.5% Bulk_ESS Tail_ESS Rhat
#> rank[No intervention]        3.89 0.32    3   4   4   4     4     2190       NA    1
#> rank[Group counselling]      1.36 0.61    1   1   1   2     3     2951     2919    1
#> rank[Individual counselling] 1.91 0.62    1   2   2   2     3     2439     2621    1
#> rank[Self-help]              2.84 0.66    1   3   3   3     4     2449       NA    1
plot(smk_ranks)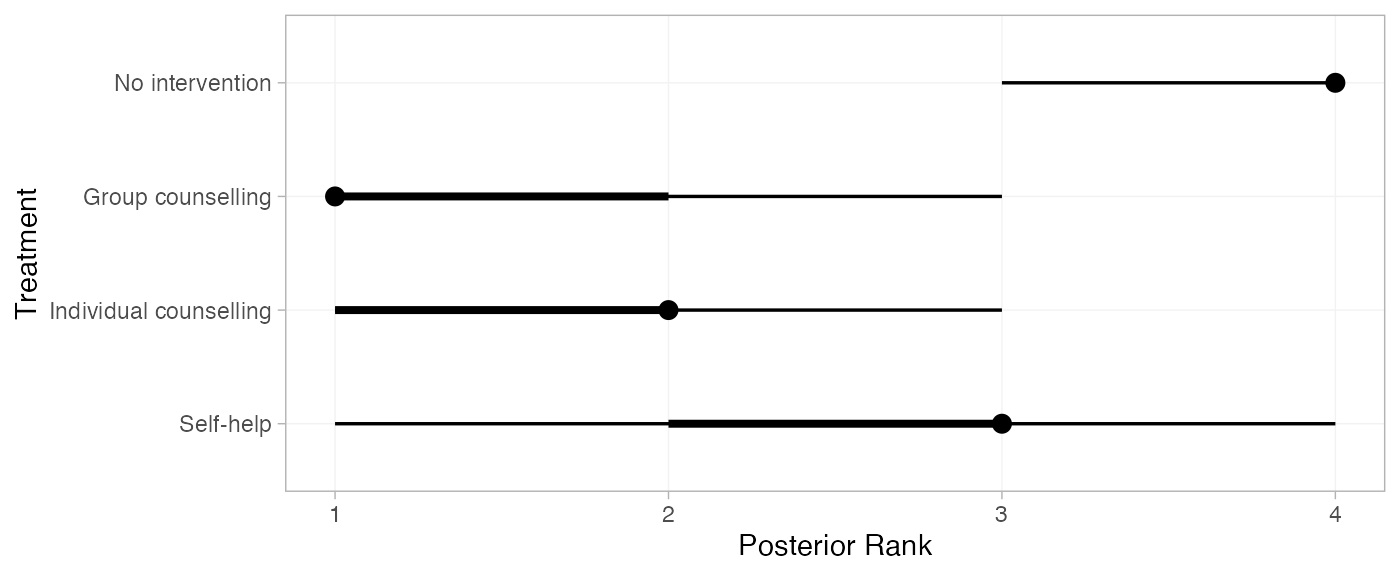
(smk_rankprobs <- posterior_rank_probs(smkfit, lower_better = FALSE))
#>                           p_rank[1] p_rank[2] p_rank[3] p_rank[4]
#> d[No intervention]             0.00      0.00      0.11      0.89
#> d[Group counselling]           0.71      0.23      0.06      0.00
#> d[Individual counselling]      0.24      0.60      0.15      0.00
#> d[Self-help]                   0.05      0.17      0.68      0.10
plot(smk_rankprobs)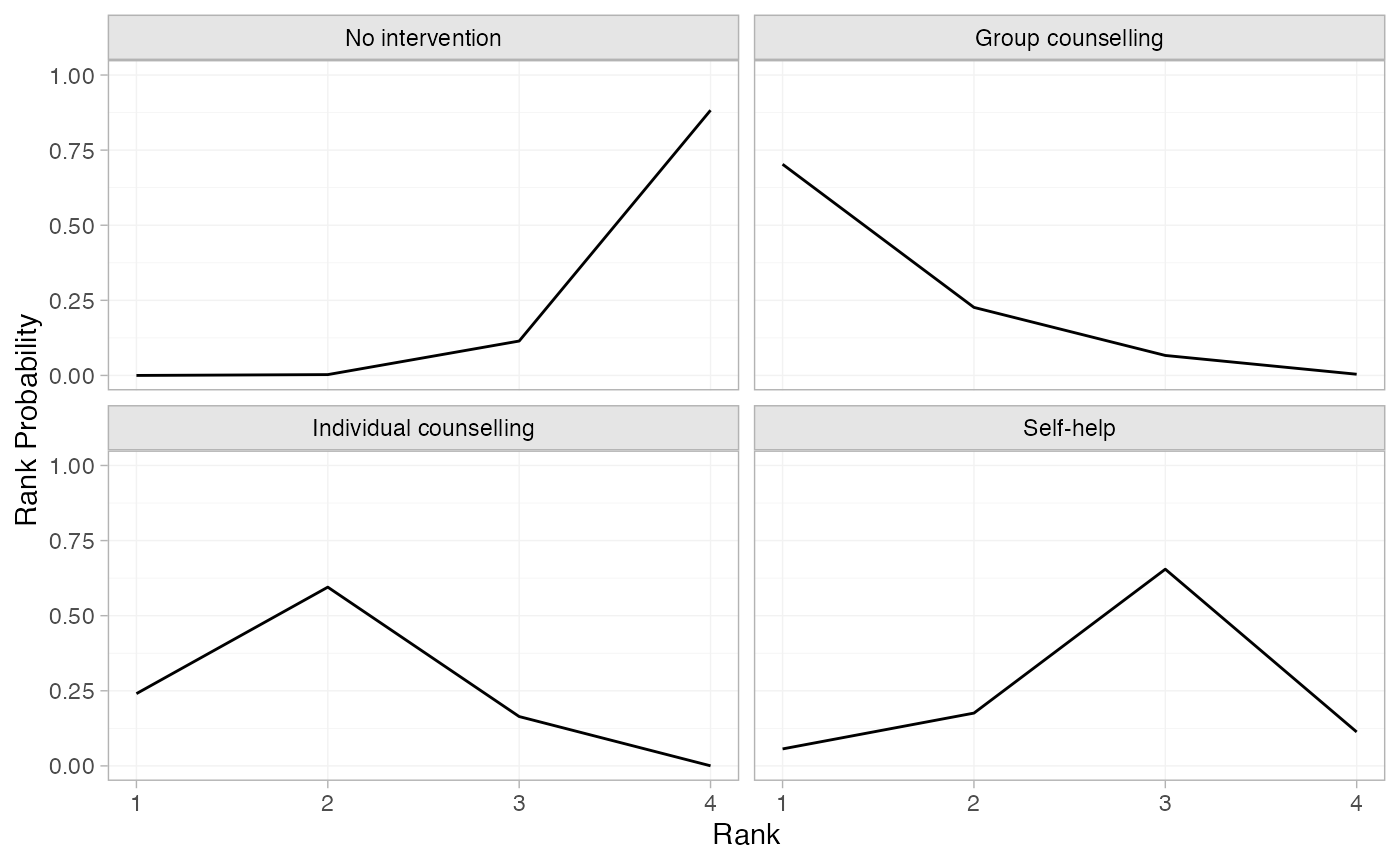
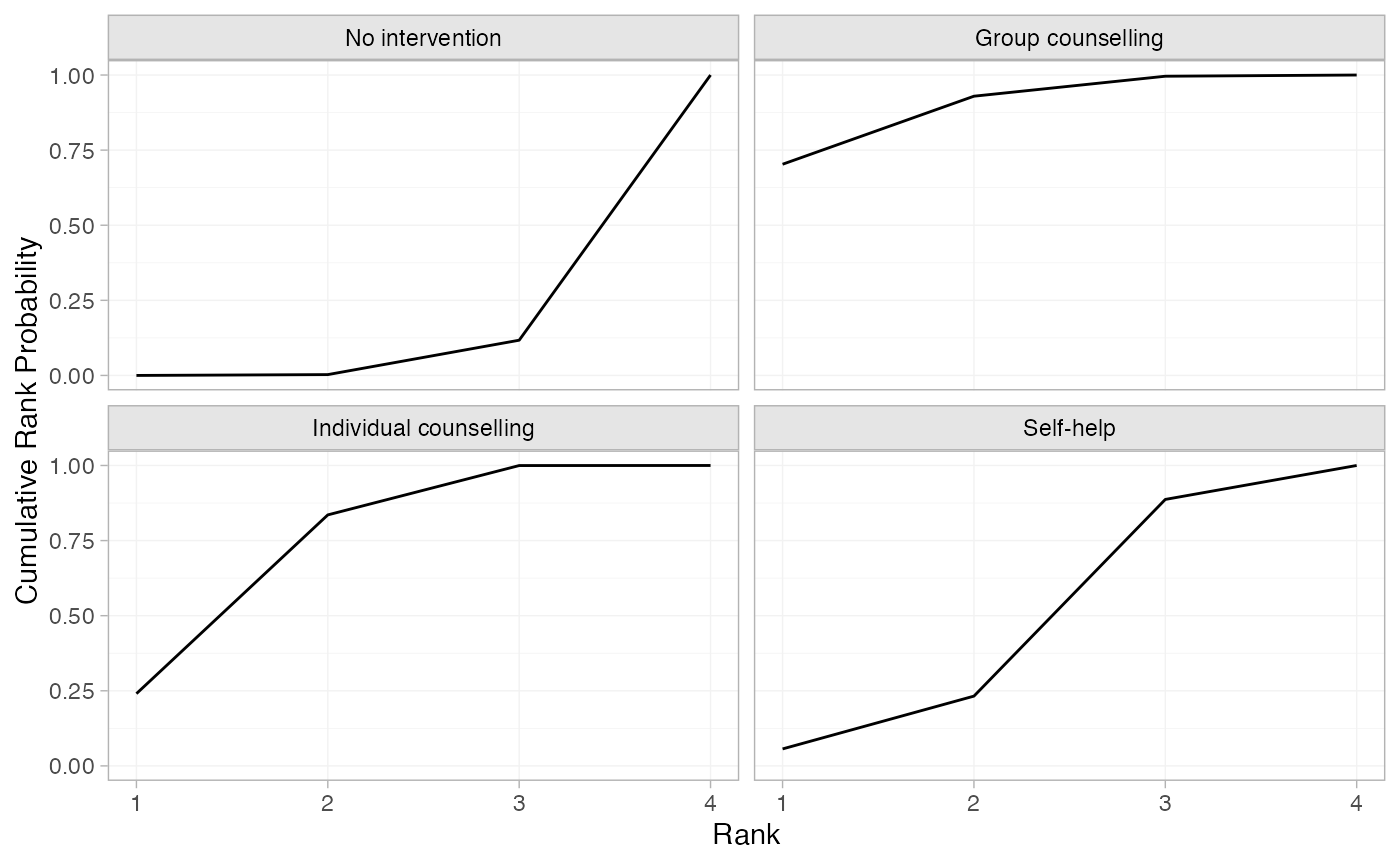
(smk_cumrankprobs <- posterior_rank_probs(smkfit, lower_better = FALSE, cumulative = TRUE))
#>                           p_rank[1] p_rank[2] p_rank[3] p_rank[4]
#> d[No intervention]             0.00      0.00      0.11         1
#> d[Group counselling]           0.71      0.94      1.00         1
#> d[Individual counselling]      0.24      0.85      1.00         1
#> d[Self-help]                   0.05      0.21      0.90         1
plot(smk_cumrankprobs)